Platform Engineering Without Platform Sprawl: How Internal Developer Portals and Golden Paths Improve Software Delivery
Build a focused platform engineering strategy with internal developer portals, golden paths and clear ownership to improve developer experience and delivery.
Why another platform is not automatically progress
A development team needs a new API service. Before writing business logic, an engineer must choose a repository template, request cloud access, configure a deployment pipeline, locate secrets, arrange monitoring, and determine who will support the service. None of these tasks is inherently difficult, but differences between teams make each request a miniature infrastructure project. Platform engineering attempts to remove that repetitive work. The risk is replacing scattered tools with another complicated system that nobody wants to use.
This distinction matters now. A March 2026 CNCF and SlashData survey of more than 400 cloud-native developers found that platform capabilities were commonly provided through collaboration among multiple teams, while dedicated platform teams were another established model. In September 2026, CNCF community guidance also highlighted the gap between having a portal and providing genuine self-service. The useful question is therefore not whether an organization has a developer platform. It is whether that platform makes a common engineering task measurably easier.
Portal, platform and golden path: three different things
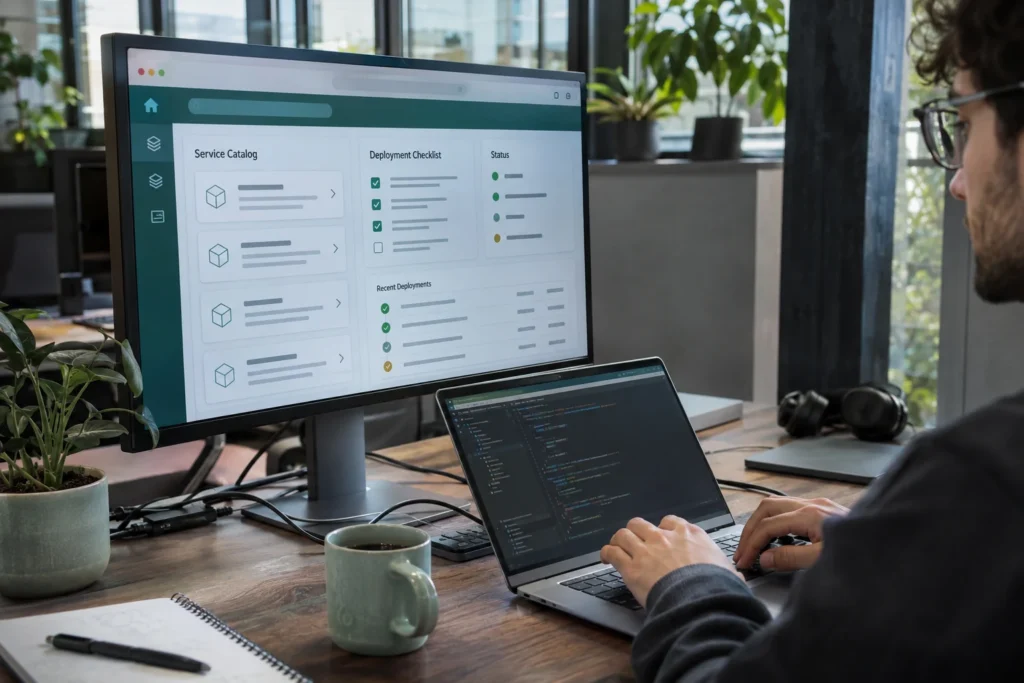
An internal developer portal is the interface where engineers discover services, documentation, templates and ownership information. An internal developer platform is the underlying collection of reusable capabilities: infrastructure provisioning, identity, deployment, policy, observability and operational controls. A portal can expose those capabilities, but a searchable catalog by itself cannot create or run an application.
A golden path is an endorsed, well-supported workflow for a repeatable job. For example, a ‘create a production API’ path may generate a repository, define a deployment pipeline, register the service in a catalog, configure baseline logging and create an ownership record. It should offer sensible defaults without blocking legitimate exceptions. The principle is to reduce the choices engineers need to make repeatedly, not to remove engineering judgment.
This separation prevents an expensive misunderstanding: buying a portal does not complete platform engineering. The real product is the reliable experience behind the interface, from request to running service.
Design around a frustrating task, not a technology catalog
The first platform feature should come from evidence. Ask application teams where they spend time waiting, which tickets are repeated, which failures return every release, and where newcomers need help. If secret access consumes hours but deployments already work, redesigning the release tool may create little value. If four teams copy and modify nearly identical pipeline files, that duplication is a stronger candidate for a supported template.
Map one process from beginning to end. For service creation, record the steps, handoffs, elapsed time, approvers, tools and failure points. Include security and operations colleagues because their controls will become part of the workflow. Then identify what can be standardized and what must remain configurable. An API handling regulated data may require a different path from an internal reporting tool, even if both are written in the same programming language.
A practical starting scope is a ‘thinnest viable platform’: one workflow that is useful, secure, documented and maintainable. CNCF platform guidance favors treating internal platforms as products. That means interviewing users, prioritizing adoption friction, publishing a roadmap and retiring features that do not solve recognizable problems.
How a production-ready golden path works
Consider a mid-sized organization running .NET APIs and background workers. A developer opens the portal, chooses ‘New ASP.NET Core API,’ enters a service name, owner and data classification, and selects an approved database option. The system creates a repository from a reviewed template, registers ownership, applies branch protection, and provides build and test pipelines. A second action requests deployment to a controlled environment using predefined permissions.
The underlying automation should be idempotent: running a provision step again should not create duplicate resources. Secrets should be issued through an approved secrets manager rather than copied into templates. Observability should include standard health checks, structured logs and a dashboard link. Provisioning should produce a traceable record so reviewers can establish what was requested, approved and created.
Backstage, for example, provides software templates for creating components and publishing generated projects. Its documentation is useful for understanding scaffolding, but no organization has to adopt a particular product to follow this pattern. A portal backed by existing APIs and infrastructure-as-code can offer the same core experience if it is reliable and discoverable.
Critically, the golden path should have an escape route. A team needing an unusual network dependency should be able to document the exception and request support, rather than quietly copying the template and bypassing its controls. Exceptions reveal what the platform has not yet learned about its users.
Governance should run with the workflow
Platform engineering can improve security when approved defaults are applied automatically. Repository protections, software dependency scanning, service identity, deployment approvals and audit events become normal steps rather than reminders buried in a checklist. The same applies to operational readiness: backup requirements, ownership, incident contacts and recovery procedures can be captured before release.
However, guardrails must be proportionate. Requiring five approvals for an isolated development environment defeats self-service. A better design uses risk-based rules: low-risk actions execute automatically; higher-risk actions request a named review; prohibited actions are blocked with a clear explanation. Policies should be versioned and tested, especially when a shared template affects many teams.
Avoid placing all operational knowledge inside the portal team. Database specialists should own database standards, security teams should define security policy, and service owners should retain accountability for their systems. The platform integrates these capabilities through clear interfaces; it should not become the only group allowed to change anything.
Measure outcomes, including hidden costs
Adoption alone is a weak success metric. A portal can have hundreds of visits while developers continue raising tickets to complete basic operations. Measure the time from a valid service request to a deployable environment, the percentage of requests completed without manual intervention, failed provisioning attempts, time spent supporting exceptions and the developer satisfaction associated with specific workflows.
Software delivery metrics provide another view. DORA’s current framework considers change lead time, deployment frequency, failed-deployment recovery time, change failure rate and deployment rework rate. Changes in these measures need careful interpretation: a golden path may reduce setup effort without immediately affecting production deployment frequency. Compare similar teams and examine trends rather than claiming causality from one dashboard.
Cost belongs in the same review. Every new template and integration adds a maintenance obligation. Count obsolete workflows, duplicated infrastructure, cloud resources provisioned but unused, and the time platform engineers spend maintaining custom exceptions. A useful platform makes a portfolio of systems easier to manage; an uncontrolled portal ecosystem adds another portfolio to maintain.
A realistic 90-day adoption plan
During the first month, select one repeated workflow, capture baseline timings and agree on minimum controls. Build a working prototype with one volunteer team rather than conducting a long procurement exercise. Keep existing operational paths available while validating the design.
In the second month, automate the complete flow, document failure recovery, and test with developers who did not build it. Ask them to provision a service without guidance. Their confusion is more useful than a polished demonstration. Involve support staff to ensure the created service can be diagnosed, patched and retired, not merely deployed.
In the third month, widen access to a few more teams and track exceptions. Publish what is supported, what is not, and who owns each capability. Make the next investment based on observed demand: database provisioning, service discovery or temporary test environments may be a better extension than a new dashboard.
The objective is not to force every team onto one perfect stack. It is to make routine work predictable while preserving flexibility where the business genuinely needs it.
Review each golden path with the people responsible for operating it. Confirm who updates its dependencies, who responds when provisioning fails, and how a team can request an exception. Keep a small record of the supported version, required permissions, recovery steps and retirement process. Test the path using a new service rather than an environment that already has the right access. Repeat that test after important changes. These checks give platform engineering teams a practical way to discover broken assumptions before they become repeated support tickets, while helping developers understand what the platform promises and where their own responsibilities begin.
The takeaway
A developer platform becomes valuable when it reduces uncertainty between ‘I need a service’ and ‘my team can safely operate it.’ Start with a painful, repeated task; expose an end-to-end golden path; incorporate security and ownership by default; and measure reduced waiting, exceptions and maintenance burden. Platform engineering succeeds when developers willingly choose the supported path because it is the easiest dependable option—not because policy leaves them no alternative.
Sources and further reading
- CNCF and SlashData, Q1 2026 CNCF Technology Radar (24 March 2026)
- CNCF, Platform engineering maturity: From toolchain to self-service (1 September 2026)
- CNCF, What is platform engineering? (19 November 2025)
- Backstage, Software Templates (documentation)
- DORA, A history of DORA’s software delivery metrics (2 January 2026)